
Spare Intel Arc A750 Runs Gemma-4-E4B at 33 Tokens in Proxmox LXC [2026]
By Indie Kings | September 21, 2026
Updated September 21, 2026: An XDA writer moved a discounted Intel Arc A750 into a Proxmox LXC with llama.cpp over Vulkan and drives Gemma-4-E4B at 33 tokens per second, per XDA. That trails a GTX 1080 by 4 to 6 tokens per second and collapses to 3.5 on Mixture-of-Experts offloads, but it costs nothing for owners with the card spare.
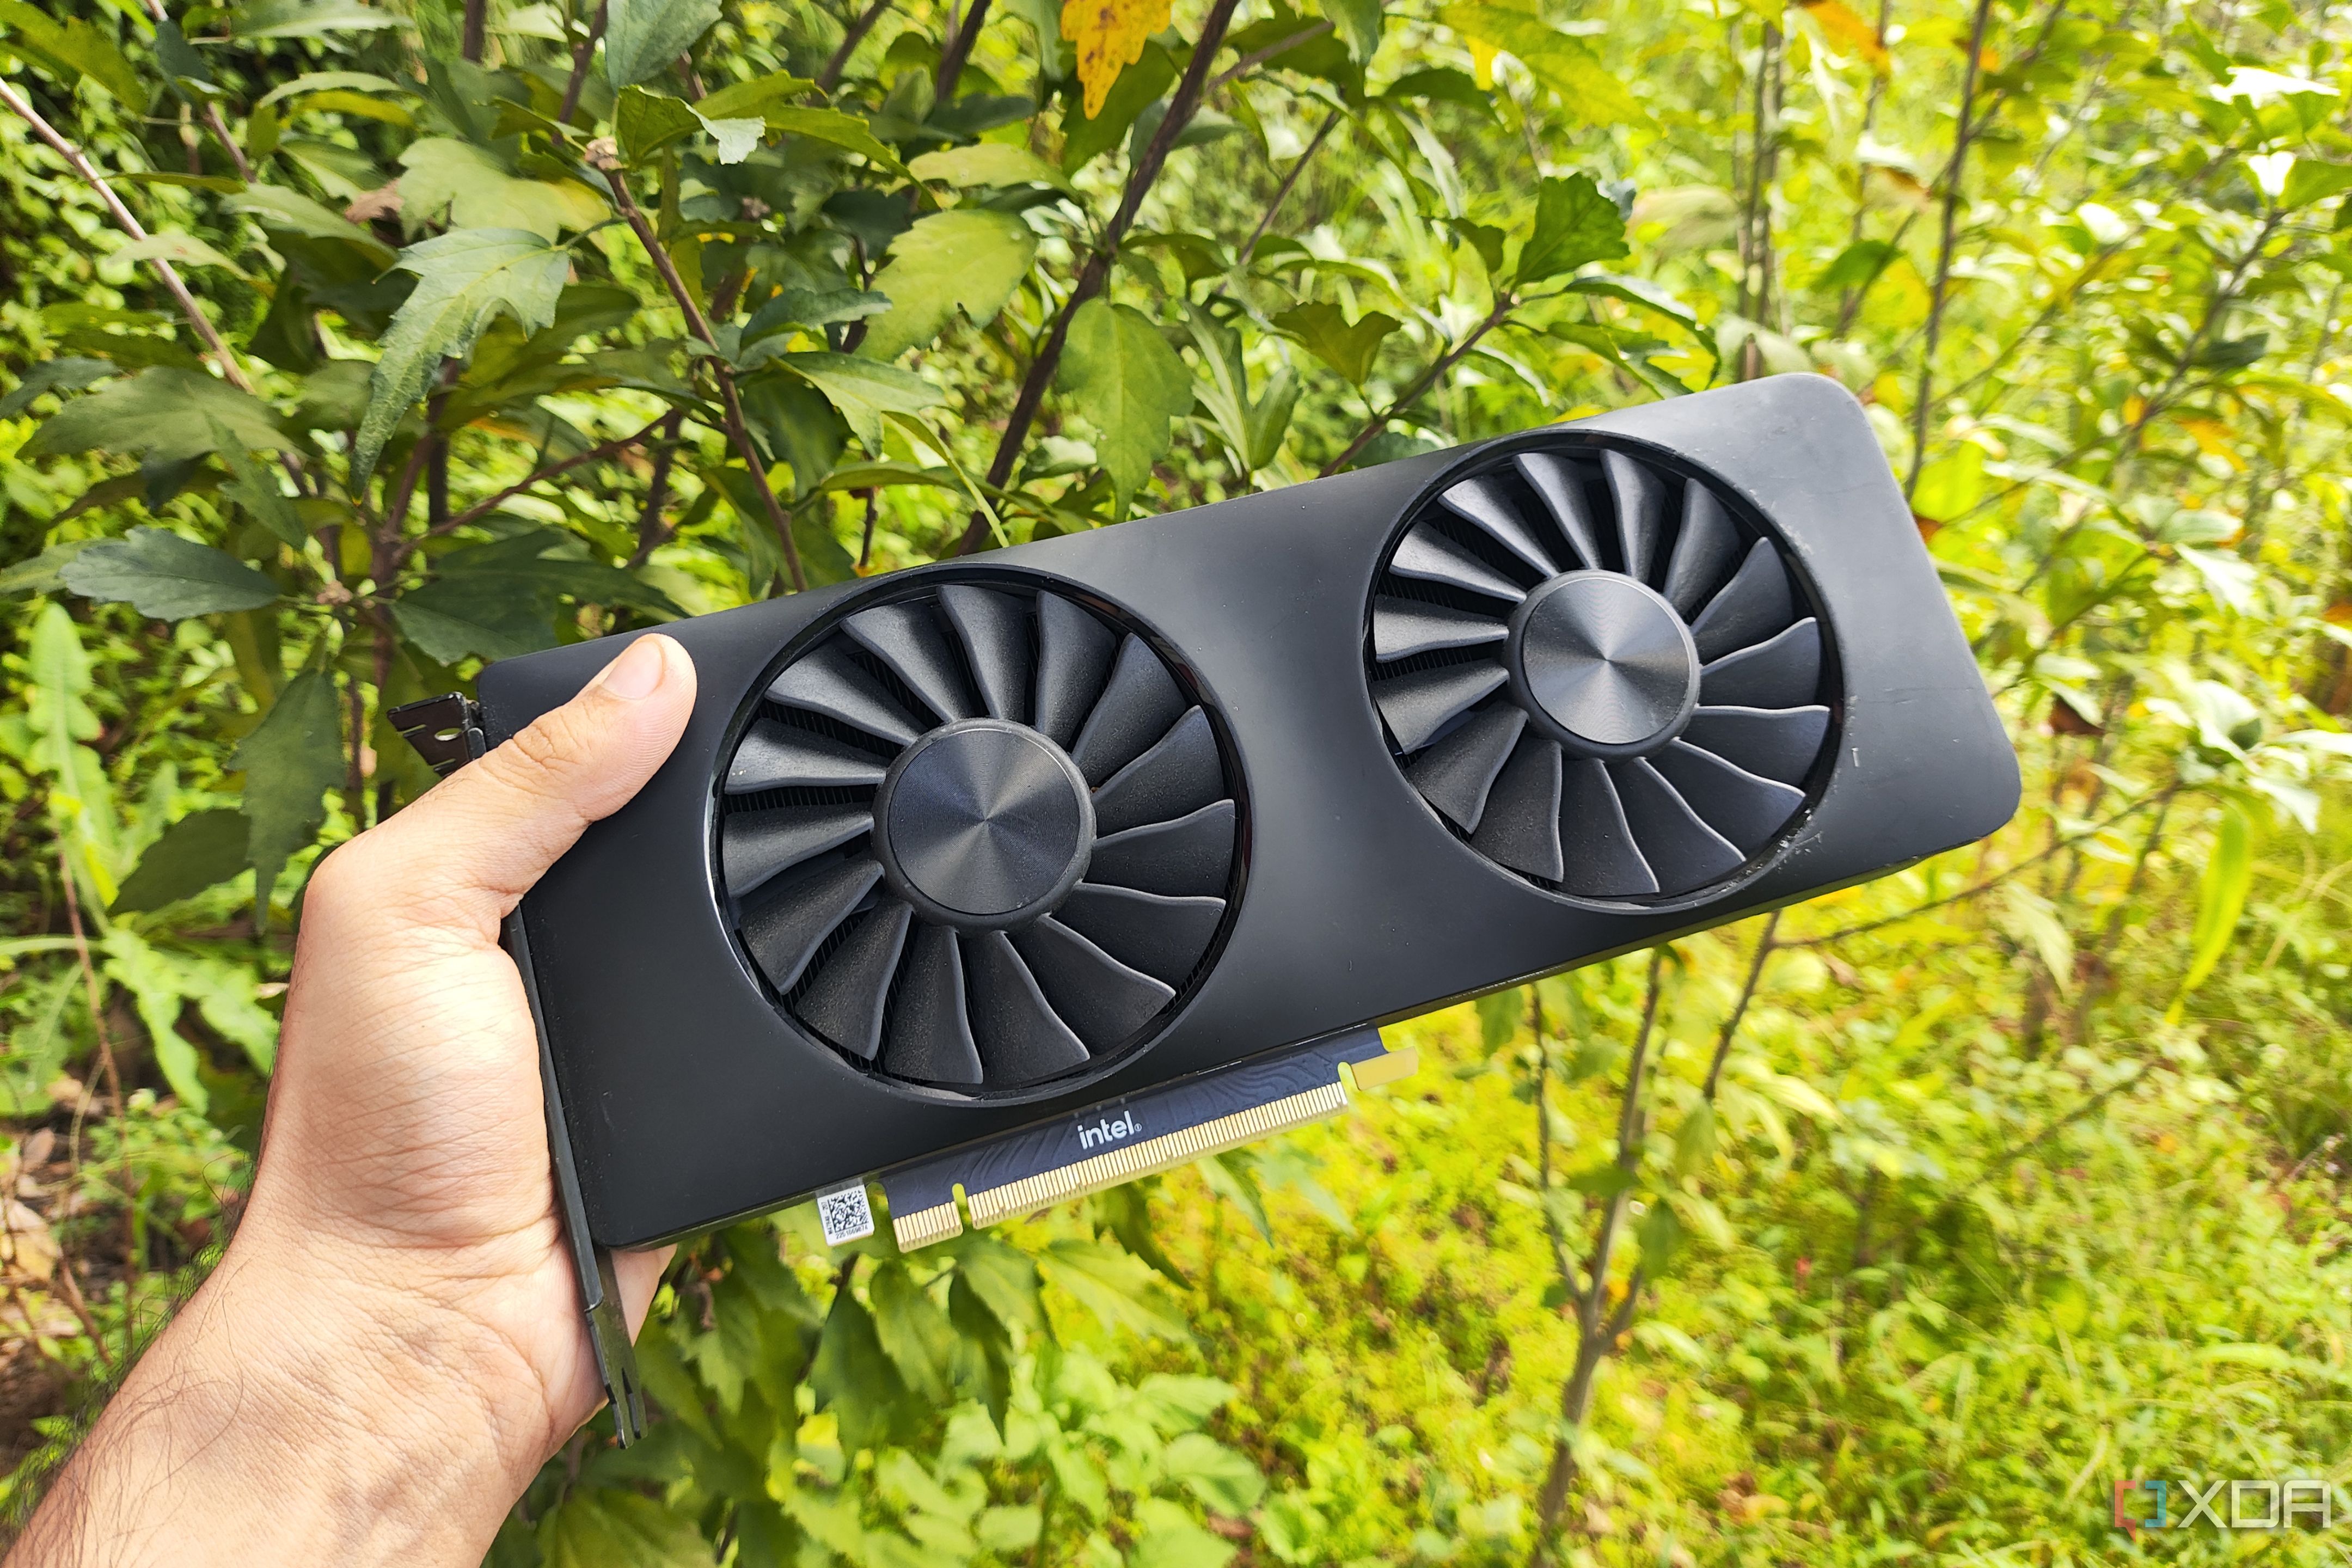
Image: The Arc A750 used for the Proxmox LLM test. Credit: Ayush Pande via XDA.
What was built on the A750
Per XDA on September 20, 2026, Ayush Pande placed an Arc A750 into an old rig with two Xeon 2650 v4 CPUs and 64GB DDR4 ECC running Proxmox. A Debian LXC hosts llama.cpp built with GGML Vulkan on.
The author chose llama.cpp over Ollama for minimal interference and Proxmox over Windows 11 bloat, per XDA. Proxmox detected the Arc card where the GTX 1080 needed manual effort.
Model under test is Gemma-4-E4B in Q4_K_M with its MMPROJ file, served on port 8081 with context 100000 and ngl 999, per the published command line.
Setup path that worked
Per XDA, host steps were mesa-vulkan-drivers plus vulkan-tools plus libvulkan1, then a community Debian VM script with GPU passthrough yes. Inside the LXC the same Vulkan drivers plus glslc, toolchains, cmake, git, and curl went in.
Verification was vulkaninfo piped to grep deviceName showing the A750 as the only device, per XDA. Then llama.cpp cloned from ggml-org with cmake Vulkan build.
Commenters suggest OpenVINO as an alternative path and A770 16GB for denser 14B models at 20 plus tokens, per the XDA thread. Untested in the piece, noted as reader tips.
| Layer per XDA | Choice | Note |
|---|---|---|
| Host | Proxmox on Xeon 2650 v4 pair, 64GB ECC | Detected Arc cleanly |
| Guest | Debian LXC with GPU passthrough | Community script assisted |
| Inference | llama.cpp with GGML Vulkan | Not Ollama, minimal overhead |
| Model | Gemma-4-E4B Q4_K_M plus MMPROJ | Context 100000 |
Gemma-4-E4B speed versus GTX 1080
Per XDA, the A750 averaged 33 tokens per second with dips to 28. The author GTX 1080 runs the same model 4 to 6 tokens faster. Images, audio, and large spreadsheets all passed.
The author expected under 15 tokens from the aged first-gen Arc, per XDA. Reality beat that by double.
For Docker productivity apps the A750 now hosts Gemma-4-E4B while the 1080 focuses on GPT-OSS-20B, per the author plan.
The MoE wall at 3.5 tokens
Per XDA, Gemma-4-26B-A4B with 30 layers offloaded to CPU managed only 3.5 tokens per second. Cutting to 20 layers crashed llama.cpp. Twenty-five layers with 10k context matched the same 3.5. GPT-OSS-20B behaved identically.
GitHub threads blame Intel GPUs with MoE offload flags, possibly a llama.cpp bug, per XDA. Either way the A750 cannot carry bulky MoE models usefully.
The author calls background-only use the ceiling for MoE here. Foreground chat at 3.5 tokens is not workable.
| Model per XDA on A750 | Result | Verdict |
|---|---|---|
| Gemma-4-E4B dense | 33 tokens avg, 28 dips | Viable daily driver |
| Gemma-4-26B-A4B MoE 30 layers | 3.5 tokens | Background only |
| GPT-OSS-20B | Same 3.5 band | Not recommended on Arc |
Should you reuse an old Arc
Reuse an A750 you own for dense small models over Vulkan llama.cpp. Do not buy one for LLMs, per the author.
Keep MoE workloads on NVIDIA with more VRAM headroom. The 1080 with 8GB still beats Arc at 14 plus tokens on 26B-A4B via offload, per XDA history.
Try OpenVINO builds before judging Intel backends final. Reader tips point there for MoE paths.
FAQ
What card was tested?
Per XDA, an Intel Arc A750 on Proxmox with a Debian LXC running llama.cpp over Vulkan.
How fast is Gemma-4-E4B?
Per XDA, 33 tokens average with dips to 28, about 4 to 6 behind the author GTX 1080.
Does MoE work?
Barely. Per XDA, 3.5 tokens on 26B-A4B and GPT-OSS-20B with offload, possibly a llama.cpp Intel bug.
What stack was used?
Per XDA, Proxmox host, Debian LXC passthrough, mesa Vulkan drivers, llama.cpp GGML Vulkan build.
Should I buy an Arc for LLMs?
No, per the author. Reuse a spare, do not purchase for this role.
What about A770 16GB?
Per XDA commenters, denser 14B models may hit 20 plus tokens. Untested in the piece.
Bottom Line
A spare A750 runs dense Gemma-4-E4B at 33 tokens over Vulkan Proxmox and fails MoE at 3.5. Reuse what you own, buy NVIDIA for bigger models.
Related: Thermalright Peerless Assassin CPU cooler overview | Thermalright Frozen Edge 360 water cooler | Nvidia GeForce 595.59 driver release issues